What is Mistral Large 4? Price, benchmarks and open-weights date
Mistral's Large 4 is a 1T-parameter, 49B-active multimodal model in public preview, with weights promised by month's end. Its benchmarks, cyber claim, caveats.
In this article
Mistral has launched a preview of its biggest model yet, and promised to open its weights within weeks. Mistral Large 4, which the company nicknames “le Chonk,” has 1 trillion parameters, 49 billion active per token, and takes images as well as text. You can try the preview API today, at $1.36 per million input tokens and $4.18 per million output tokens; the weights are promised “by the end of this month.” This article covers what Mistral says the model is, how its own benchmarks look, the cybersecurity claim that anchors the launch, and what remains unverified. We read the full announcement; we have not run the model.
What does Mistral Large 4 offer?
| Item | What Mistral says |
|---|---|
| Architecture | Open-weight hybrid instruct-and-reasoning mixture-of-experts model, natively multimodal; 1 trillion parameters, 49 billion active |
| Training | From scratch on 3,800 NVIDIA Grace Blackwell GPUs in Mistral’s own European datacenters |
| Languages | A significant share of training data in more than 160 languages, including every official EU language |
| Preview | Public preview API in Mistral Studio, served from the same European infrastructure |
| Price | $1.36 per million input tokens, $4.18 per million output tokens |
| Weights | “By the end of this month,” with more detail on architecture, benchmarks and post-training |
| License | Not stated in the announcement |
Mistral frames the launch around sovereignty: a European deployment that it says it operates end to end, under European law. It also calls the model the first milestone on the roadmap funded by its €3 billion Series D.
How does Mistral Large 4 perform on benchmarks?
These are Mistral’s figures. Most use public benchmarks, and some come from third-party evaluators:
| Area | Result reported by Mistral |
|---|---|
| Coding | 61.7% on DeepSWE v1.1; 59.4% on SWE-Atlas-QnA; 28.3% on Terminal-Bench 4; a combined Coding Agent Index of 49.8%, ahead of DeepSeek V4 Pro 0813 and Qwen3.8 Max |
| Agentic work | 59.9% on AutomationBench (657 business workflows), ahead of Kimi K3, MiMo-V2.6-Pro and DeepSeek V4 Pro; 1,393 Elo on AA-Briefcase |
| Vision | 42% against 41% for GPT-6 Astra on the Dense 200 visual-grounding test |
| Law and finance | Ahead of GPT-6 Astra on two vals.ai evaluations; ahead of all open models on Harvey’s Legal Agent benchmark |
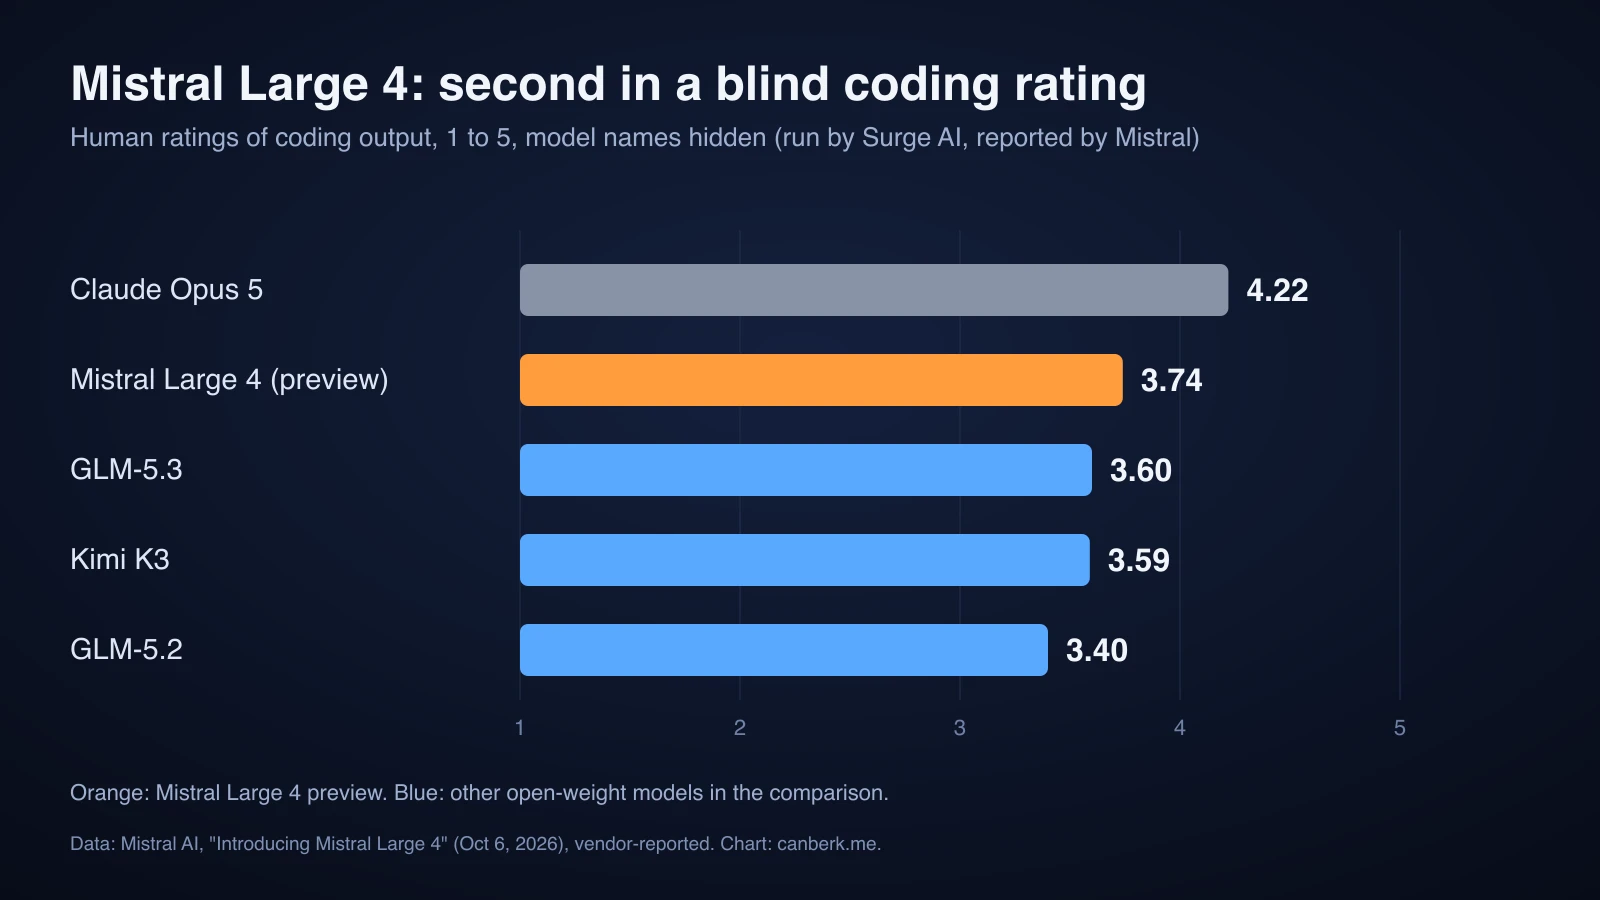
In a blind human evaluation run with Surge AI, professional annotators rated coding output on a 1 to 5 scale with model names hidden. Mistral Large 4 preview came second of five at 3.74, behind Claude Opus 5 (4.22) and ahead of GLM-5.3 (3.60), Kimi K3 (3.59) and GLM-5.2 (3.40). In an internal comparison with GLM-5.3, annotators preferred it for computer-aided design and STEM tasks and found it on par or close in finance and coding.
Why does Mistral say Large 4 is strong at cybersecurity?
This is the center of the announcement. Mistral says Large 4 ranks among the top five models on the Artificial Analysis Cyber Index, which it describes as an independent evaluation of finding and fixing flaws in real software, and leads open-weight models developed outside China “by a wide margin.” On one test of that index, which asks a model to reproduce a real vulnerability and then patch it, Mistral says it scores 82%, “the highest of any model,” and it solves 93% of the challenges in Cybench, a set of 40 exercises from security competitions.
Mistral also says that several leading closed models, including Claude Opus 5.5 and GPT-6 Astra, score near zero on that same test “because they refuse to perform the task,” arguing that provider-level refusals can block legitimate defensive work. The refusal explanation is Mistral’s. It also says that, during the preview, it is red-teaming the model with cybersecurity leaders, vetted partners and state authorities, who get a version with reduced moderation and expanded cyber capabilities. It adds that the model’s average refusal rate on malicious cyber prompts from JailbreakBench, StrongREJECT and AgentHarm is higher than for any open-weight model.
How does Mistral rate Large 4’s safety?
Mistral reports that the model resists 93.3% of attacks on Lakera’s public B3 agent-security benchmark, “saturated” its internal tests for indirect prompt injection, and scored 1.691 out of 2 on the KORA benchmark, its highest among open models. These are self-reported and the comparison models are Mistral’s choice.
How was Mistral Large 4 trained?
Mistral describes a reinforcement-learning library that combines tasks from single-turn chat to long-horizon tool use, with verification from reward models, unit tests, LLM judges and static checks. At about 3,000 GPUs, it says a single training run produces roughly 33 billion tokens a day, around 16 billion of them trainable, and that the run behind the preview is still in flight with no sign of saturation. It expects “large and rapid improvements” in the coming weeks.
When will Mistral Large 4’s weights be released?
The weights, the architecture details, more benchmarks and the post-training methodology are all promised by the end of the month, and Mistral says the model will become the base for specialized Mistral models. Until then, nobody outside Mistral and its partners can inspect or test the model offline, and the license is unknown.
What to keep in mind
These are our observations:
- Everything is vendor-reported. Third-party names such as Artificial Analysis, vals.ai, Surge AI and Lakera appear, but Mistral chose the tests, the comparison models and which results to show.
- The comparison set matters. Mistral says the model “significantly outperform[s] any open-weight model developed in the US or Europe,” a scope that excludes Chinese models. Separately, the table in Reflection’s Beam announcement lists higher DeepSWE v1.1 scores for Kimi K3 (68.0) and DeepSeek V4.1 Flash (74.2) than Mistral’s 61.7; the benchmark settings and model versions differ, so treat cross-vendor rankings carefully.
- “Refusal” is not the whole story in cyber. Whether a model should do offensive-looking security work is a policy choice; Mistral’s pitch is that open weights let organizations set their own policy, while the preview’s reduced-moderation version goes only to vetted partners. Our coverage of Anthropic’s GLM-5.3 cyber report shows the same debate from the other side.
- It will not run on a desktop. By our arithmetic, 1 trillion parameters at 4 bits each is about 500GB for the weights alone; the 49B active figure speaks to speed, not memory.
- Two open-weight launches, both pending. This and Reflection’s Beam both promise weights later this month; wait for the files before judging either.
Editorial review: October 7, 2026 (AI). Prepared from Mistral’s announcement “Introducing Mistral Large 4” (October 6, read in full through a browser) the same day. We did not run the model; no weights, technical report or independent results were available. All benchmark, safety and training figures are Mistral’s. The cover uses Mistral’s own logo on a card we made; the chart in the body is ours, from Mistral’s reported Surge AI ratings. Mistral’s own hero image and cover card were not used (an abstract grid and a “#1 in Sovereign AI” slogan). The size arithmetic and “What to keep in mind” are ours.
Sources
- Introducing Mistral Large 4 ↗Mistral AI
Created with AI assistance.
Suggest a correction
Found an error or a missing source? Send a private suggestion to the editor. It will be reviewed and will not appear as a public comment. No name, email or account is needed.


Send us a message