Reflection unveils Beam, a 501B model with open weights due this month
Reflection says Beam, a 501B-parameter model with 23B active, will get Apache 2.0 weights this month. Benchmarks, training scale and what is still unreleased.
In this article
The AI lab Reflection has announced Beam, a 501-billion-parameter model it calls its first open-weight release. The catch is in the timing: the October 5 announcement says the weights, technical report and model card will come “later this month,” and for now only a waitlist is open. This article covers what Reflection says Beam is, how its own benchmarks look, how it says it trained the model, and what cannot be checked yet. We read the full announcement; we have not run the model, and there is nothing to run yet.
What is Beam?
| Item | What Reflection says |
|---|---|
| Architecture | Sparse mixture of experts, 501B parameters in total, 23B active per token, 52 layers, interleaved local and global attention |
| Focus | Coding, reasoning and agentic workloads; text-only |
| Pretraining | 23.8 trillion tokens from the web and proprietary licensed datasets |
| Context | Midtraining extends the effective context to 1M tokens |
| License | Weights under Apache 2.0, promised this month |
| Availability | Early-access waitlist now; model in final red-teaming and evaluation |
Reflection says Beam is the first model in a series and that it is already training the next one.
How does Beam compare, by Reflection’s numbers?
Reflection’s own table, which marks scores it does not have as “NR” (not reported):
| Benchmark | Beam | GLM 5.2 | GLM 5.3 | Kimi K3 | Qwen 3.8 Max | DeepSeek V4.1 Flash |
|---|---|---|---|---|---|---|
| DeepSWE v1.1 | 44.4 | 44.0 | 61.0 | 68.0 | 51.0 | 74.2 |
| Terminal Bench v2.1 | 80.1 | 81.0 | 88.2 | 88.3 | 86.6 | 90.6 |
| SWE Bench Pro v1 | 65.5 | 62.1 | NR | NR | 67.7 | NR |
On SWE Bench Verified Beam scores 80.9, against 77.6 for Inkling and 70.7 for Nemotron 3 Ultra, the only others with a figure. In Reflection’s words Beam “advances the Western open-weight frontier,” is competitive with larger open models like GLM 5.2 and approaches Qwen 3.8-Max on coding and agentic tasks, while frontier open models such as Kimi K3 remain ahead on raw capability. It also shows a demo in which Beam gets 95.5% coverage on a viral land-and-water puzzle, between Opus 5 and Fable 5.
What does “efficient” mean here?
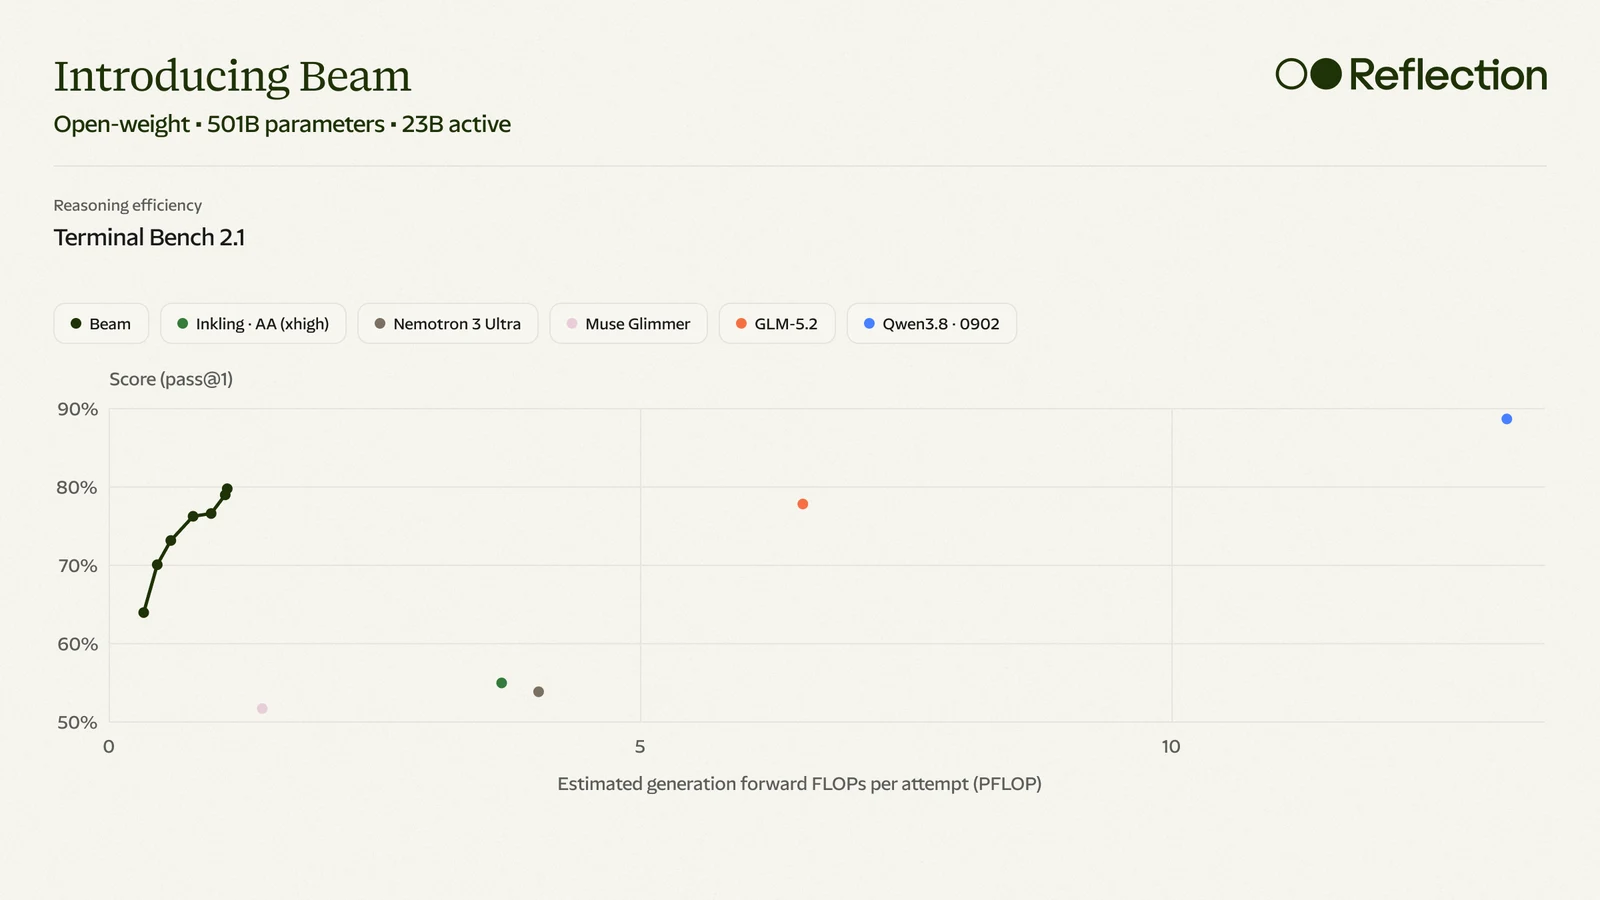
Reflection’s headline claim is efficiency: on advanced reasoning benchmarks it says Beam matches GLM-5.2 while using 3 to 4 times less inference compute. The estimate is generation FLOPs, roughly twice the active parameters times the mean tokens generated per attempt, using Artificial Analysis and DataCurve data for the other models. Reflection says it excludes prompt prefill, attention that depends on context length, and serving overhead, so it is “an approximate compute comparison rather than measured inference cost.” A reasoning-effort setting lets users trade length against performance.
How was it trained?
Reflection gives unusually concrete infrastructure numbers, all its own:
- Pretraining: a 6,144-GPU GB300 NVL72 cluster in under four weeks, nine semi-automatic rewinds, and 92.3% goodput late in the run.
- Reinforcement learning: 10.5K GB300 GPUs for four weeks, more than 100 million rollouts of up to 256K tokens, about 1.3 billion sandboxes and nearly one million environments, with fully asynchronous training that stayed stable on samples up to a day old. Reflection calls it one of the largest RL runs by an open lab.
- Platform: an average of 110K concurrent rollouts, up to 170K concurrent sandboxes, new weights reaching the inference fleet in a median of about 12 seconds, and 71 inference incidents handled without stopping training.
What is not released yet?
The weights, technical report, model card and developer tools are all promised “later this month,” along with launch partners and integrations with open-source libraries and harnesses. Safety results are to be published in the report, and Reflection says it will open-source the safety evaluations it used. Until then, nobody outside the company can test the benchmark claims.
What to keep in mind
These are our observations:
- “Open-weight” is a promise for now. The weights are expected this month, so the headline describes a plan, not a download.
- The numbers are Reflection’s. The comparison uses other labs’ scores from third-party sources, leaves many cells blank, and shows Beam behind Kimi K3 and GLM 5.3 on the coding benchmarks listed. Its strongest argument is cost, not raw score.
- It will not run on a desktop. By our arithmetic, 501 billion parameters at 4 bits each is about 250GB for the weights alone, which is why the 23B active figure speaks to inference speed rather than memory. That is far beyond a pair of 64GB DGX Spark units; this is our calculation, not Reflection’s.
- Wait for the report. The technical report and independent tests will say more than a launch post.
Editorial review: October 6, 2026 (AI). Prepared from Reflection’s announcement “Introducing Beam” (October 5, read in full through a browser) the same day. We did not run the model; no weights, technical report or model card were available. All benchmark, efficiency and training figures are Reflection’s. The cover is Reflection’s own card, reproduced with credit and a link to the source; its chart is Reflection’s estimate. The size arithmetic and “What to keep in mind” are ours.
Sources
Created with AI assistance.
Suggest a correction
Found an error or a missing source? Send a private suggestion to the editor. It will be reviewed and will not appear as a public comment. No name, email or account is needed.


Send us a message